187 confirmed memory-safety findings, from a 4B decision model inside a purpose-built harness.
Look Here, Then Decide
Small Decision Models in a Harness Find Memory-Safety Vulnerabilities at Scale on Commodity GPUs
By Tim De Wachter (CTO), Kyryl Volkov (AI Security Researcher), Myrto Eleftheria Gkogkou (AI Agent Developer) and Mathieu Huysman (CCO). Deus Rex Research.
What a small model found.
- 187
- memory-safety findings confirmed, 86% rated critical or high
- 4,000+
- open source C and C++ projects searched
- 3
- desktop-class GPU systems, with no frontier model in the search
- 9.8
- decisions per second on a consumer gaming GPU
Each figure is defined in the paper (Sections 6.4 and 6.5). A confirmed finding reproduced as an AddressSanitizer crash in a reproducer and again on a hardened build, and was accepted in review.
The abstract.
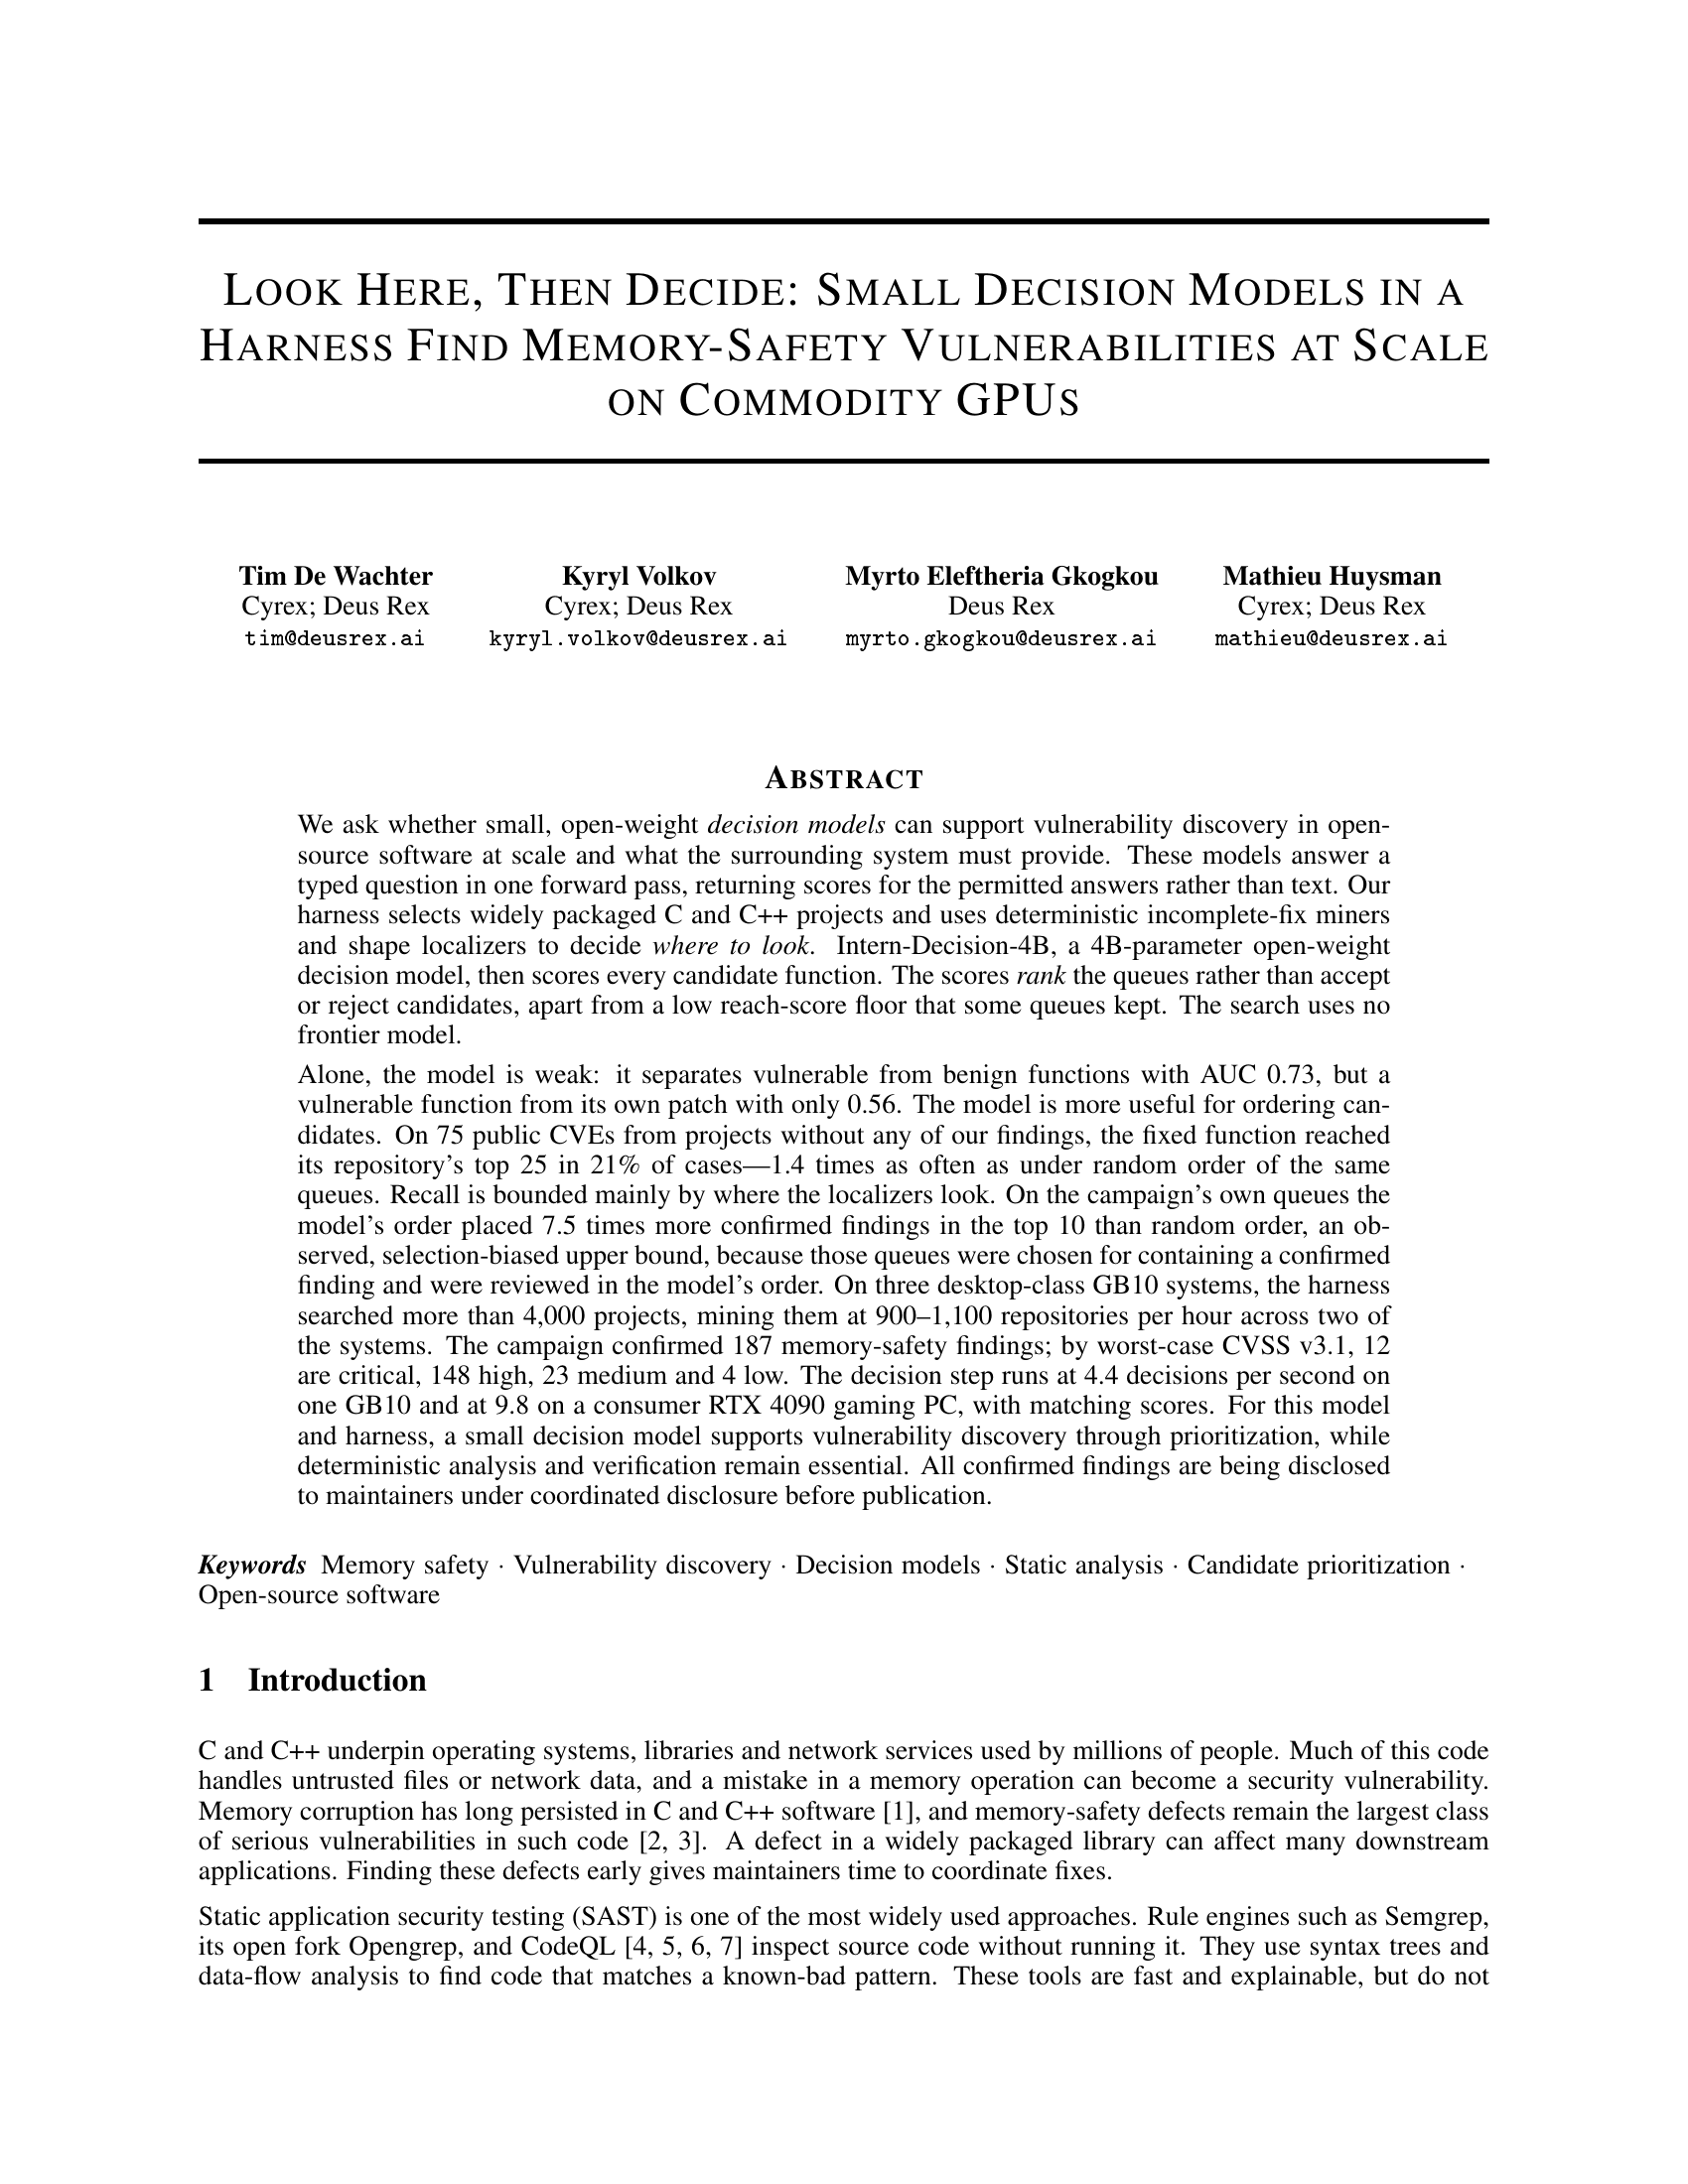
We ask whether small, open-weight decision models can support vulnerability discovery in open-source software at scale and what the surrounding system must provide. These models answer a typed question in one forward pass, returning scores for the permitted answers rather than text. Our harness selects widely packaged C and C++ projects and uses deterministic incomplete-fix miners and shape localizers to decide where to look. Intern-Decision-4B, a 4B-parameter open-weight decision model, then scores every candidate function. The scores rank the queues rather than accept or reject candidates, apart from a low reach-score floor that some queues kept. The search uses no frontier model.
Alone, the model is weak: it separates vulnerable from benign functions with AUC 0.73, but a vulnerable function from its own patch with only 0.56. The model is more useful for ordering candidates. On 75 public CVEs from projects without any of our findings, the fixed function reached its repository’s top 25 in 21% of cases: 1.4 times as often as under random order of the same queues. Recall is bounded mainly by where the localizers look. On the campaign’s own queues the model’s order placed 7.5 times more confirmed findings in the top 10 than random order, an observed, selection-biased upper bound, because those queues were chosen for containing a confirmed finding and were reviewed in the model’s order. On three desktop-class GB10 systems, the harness searched more than 4,000 projects, mining them at 900 to 1,100 repositories per hour across two of the systems. The campaign confirmed 187 memory-safety findings; by worst-case CVSS v3.1, 12 are critical, 148 high, 23 medium and 4 low. The decision step runs at 4.4 decisions per second on one GB10 and at 9.8 on a consumer RTX 4090 gaming PC, with matching scores. For this model and harness, a small decision model supports vulnerability discovery through prioritization, while deterministic analysis and verification remain essential. All confirmed findings are being disclosed to maintainers under coordinated disclosure before publication.
Read the full paperCareful harness design, more than model size, is what makes early, large-scale vulnerability finding affordable for defenders and maintainers.
In plain English
Most AI vulnerability research relies on very large, expensive models reasoning through code one file at a time. We asked a different question: can a small, fast model find real vulnerabilities at scale, if the system around it is designed well? The answer was yes. The lesson: the design of the system matters more than the size of the model.
Why it matters
The same principle runs through the Deus Rex platform: the system that decides where to look, and proves what it finds, matters more than the size of any model inside it.
No affected project is named until its fix is public.
Inside the paper.
- 1IntroductionWhy small decision models, and the research question.
- 2BackgroundDecision models and System-One-style inference, signals for vulnerability discovery, and ranking.
- 3Related workWhere this sits among rule engines, learned detectors and LLM-based discovery.
- 4Method: the harnessProject selection, incomplete-fix miners, shape localizers, and two questions used to rank.
- 5Experimental setupResearch questions, datasets, comparisons, metrics, severity and hardware.
- 6ResultsClassification, prioritisation, recall on known CVEs, throughput and cost, and the campaign's outcomes.
- 7Responsible disclosure and ethicsHow every finding is handled before publication.
- 8LimitationsWhat the study does not show.
- 9Conclusion
Questions about the paper.
A decision model answers a typed question about one input in a single forward pass and returns a score for each permitted answer, instead of generating text. Each decision costs one prefill and no decoding, so its output can order a queue directly. The study uses Intern-Decision-4B, a 4B-parameter open-weight decision model.
Put the harness to work.
Talk to the team behind the paper, or see what the same principles find in your own systems.